Educators
A teacher has a historical portrait or character illustration and needs a short spoken introduction.
The image becomes a more engaging explainer opening without filming a new presenter.
text to lip sync ai freeStill image workflow
Vidione makes a new talking-avatar video from one photo, your script and a selected voice after subscription; it does not accept a replacement voice track for an existing video. Start with a clear face, choose suitable audio, and send the setup to Lipsync for creation.
Partner workflow: Vidione creates paid talking-avatar video from a photo, script and voice, or a single AI video shot after sign-in and subscription. It cannot change the speech or lip movements in an already recorded video. These links transfer no footage or prompt.
Vidione generates a talking avatar from a photo, script and voice after sign-in and subscription; it does not re-dub existing video. This guide transfers no footage or prompt.
Choose the input and output style that best matches your project.
Start from written dialogue when you want the words to shape the speaking performance.
Explore a drawn or designed character workflow when a real portrait is not the right starting point.
Compare broader AI video workflows for scenes that need more than one still image.
Use a single portrait as the visual base for a focused speaking clip.
A still image can become a useful video asset when the voice, expression, and message need to travel together.
A teacher has a historical portrait or character illustration and needs a short spoken introduction.
The image becomes a more engaging explainer opening without filming a new presenter.
text to lip sync ai freeA campaign already has a product mascot or portrait but lacks a compact social video.
The existing visual gets a voice-led format that can support a short announcement.
lip sync animationA creator wants to give a character image a line of dialogue for a skit, story, or reaction.
The photo becomes a simple performance asset instead of remaining a static post.
text to lip sync ai freeA project has approved artwork and a recorded message but limited time for a new shoot.
The team can test a talking-image concept before planning a larger production.
lip sync animationKeep the setup simple: choose the visual, provide the speech, then review the resulting clip.
Use a front-facing image where the mouth and lower face are visible. A well-lit, high-resolution face gives the workflow more useful visual information.
Provide dialogue or a concise prompt describing the line, tone, and intended delivery. Keep the message specific enough to review.
Check that the mouth movement follows the audio and that the expression suits the message. Adjust the source or direction if the result feels off.
This format is intentionally compact: one visual base, one speech direction, and one reviewable video result.
The main change is not the portrait itself; it is the addition of timed speech and visible mouth movement.
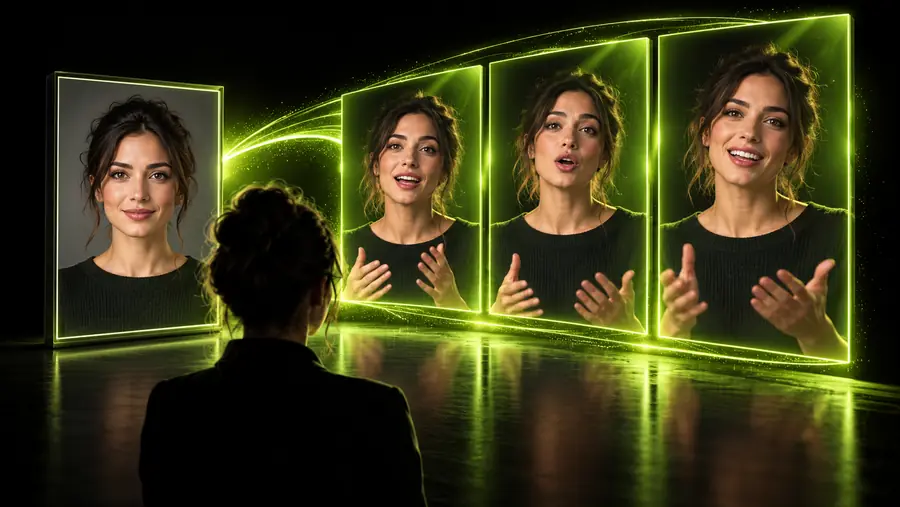
Use a face with a visible mouth and a clean, intentional audio track.
The two formats serve different jobs. The photo preserves a single visual moment, while the video adds timing, speech, and movement for communication.
Photo input
One still frame
Lip-synced video
A timed speaking scene
Photo input
No built-in spoken performance
Lip-synced video
Speech guides the visible mouth movement
Photo input
Portraits, references, thumbnails, and artwork
Lip-synced video
Introductions, dialogue, announcements, and short stories
Photo input
Clear subject and intentional composition
Lip-synced video
Clear subject plus suitable spoken direction
Photo input
Framing, clarity, and expression
Lip-synced video
Audio timing, mouth movement, and message fit
Photo input
Mostly visual adjustments
Lip-synced video
Visual and speech changes may both affect the result
A photo workflow is useful, but it does not remove the need for a suitable source image or thoughtful review.
A face that is heavily obscured, turned away, blurry, or cropped at the mouth may not provide enough information for convincing movement.
WorkaroundChoose a front-facing, well-lit image with the lower face visible.
The result adds visible speech movement, but it does not automatically reproduce hand gestures, body acting, or a complete filmed scene.
WorkaroundUse a filmed or animated workflow when the project depends on full-body performance.
Muffled, overlapping, or poorly directed speech can make the final clip harder to judge and less coherent.
WorkaroundUse a clean voice track or rewrite the direction before generating.
Small changes in the image, wording, or delivery can affect the outcome, so review remains part of the process.
WorkaroundTest a short message first and refine the source or prompt deliberately.
Bring a clear portrait and a focused spoken idea to Lipsync. The photo lip sync video maker workflow is designed for testing a talking-image concept without turning the setup into a full production.
Answers to the practical question of adding lip sync to a still image.
Start with a clear, front-facing photo where the mouth is visible, then provide the speech or direction for the scene. The workflow uses that still image as the visual base and creates a video with mouth movement timed to the spoken content.
A well-lit portrait with a visible lower face is the strongest starting point. Avoid heavy blur, extreme side angles, blocked mouths, and crowded compositions because they make the speaking result harder to evaluate.
Yes, written dialogue can give the scene a defined message when it is passed as the speech direction for the project. Keep the line concise and specify the intended tone so the resulting clip has a clear purpose.
No. The main change is a speaking video effect centered on the face and its timing with the audio. It does not automatically create full-body acting, hand gestures, or a complete filmed performance.
Review the source image and the audio first. Use a clearer portrait, make sure the mouth is unobstructed, shorten or clarify the spoken direction, and test a focused message before expanding the scene.